
工作流与智能体(Workflows and agents)
本指南回顾了常见的工作流和智能体模式。
- 工作流具有预定的代码路径,并设计为按特定顺序运行。
- 智能体是动态的,可自行定义流程和工具使用方式。
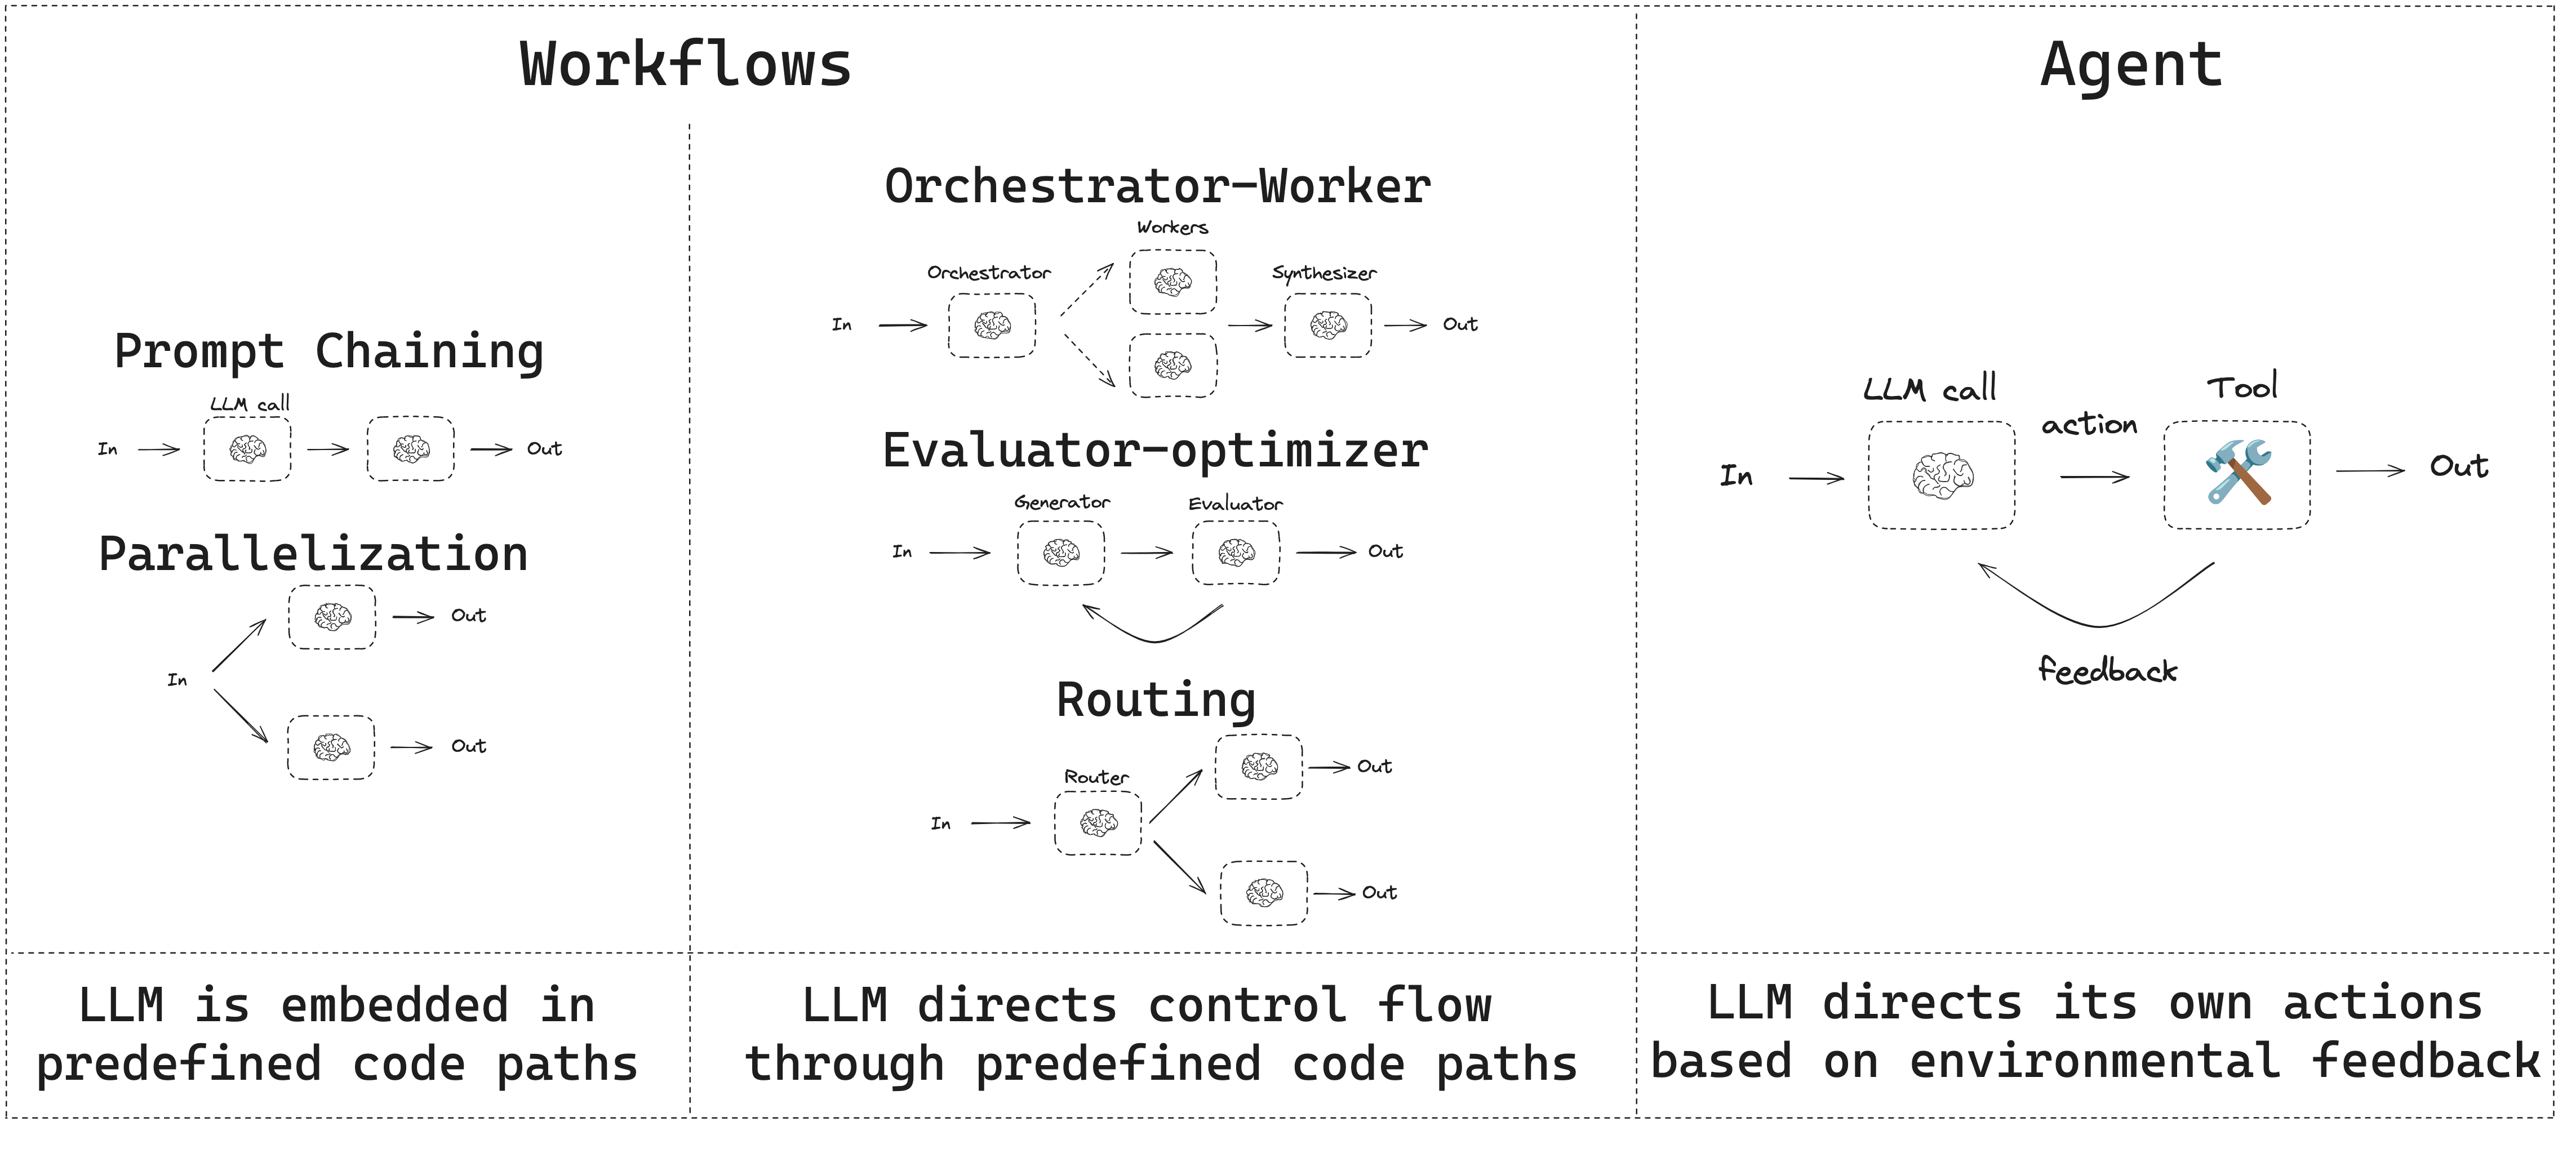
LangGraph 在构建智能体和工作流时提供了多项优势,包括持久化(persistence)、流式传输(streaming)以及对调试和部署(deployment)的支持。
TIP
使用 LangSmith 跟踪并比较这些工作流模式。按照跟踪快速入门查看数据如何在各个步骤中流动。我们还建议你设置 LangSmith Engine,它可以监控你的跟踪、检测问题并提出修复建议。
设置
要构建工作流或智能体,你可以使用支持结构化输出和工具调用的任何聊天模型。以下示例使用 Anthropic:
- 安装依赖项:
npm install @langchain/langgraph @langchain/corepnpm add @langchain/langgraph @langchain/coreyarn add @langchain/langgraph @langchain/corebun add @langchain/langgraph @langchain/core- 初始化 LLM:
import { ChatAnthropic } from "@langchain/anthropic";

const llm = new ChatAnthropic({
  model: "claude-sonnet-4-6",
  apiKey: "<your_anthropic_key>"
});
LLM 及其增强机制
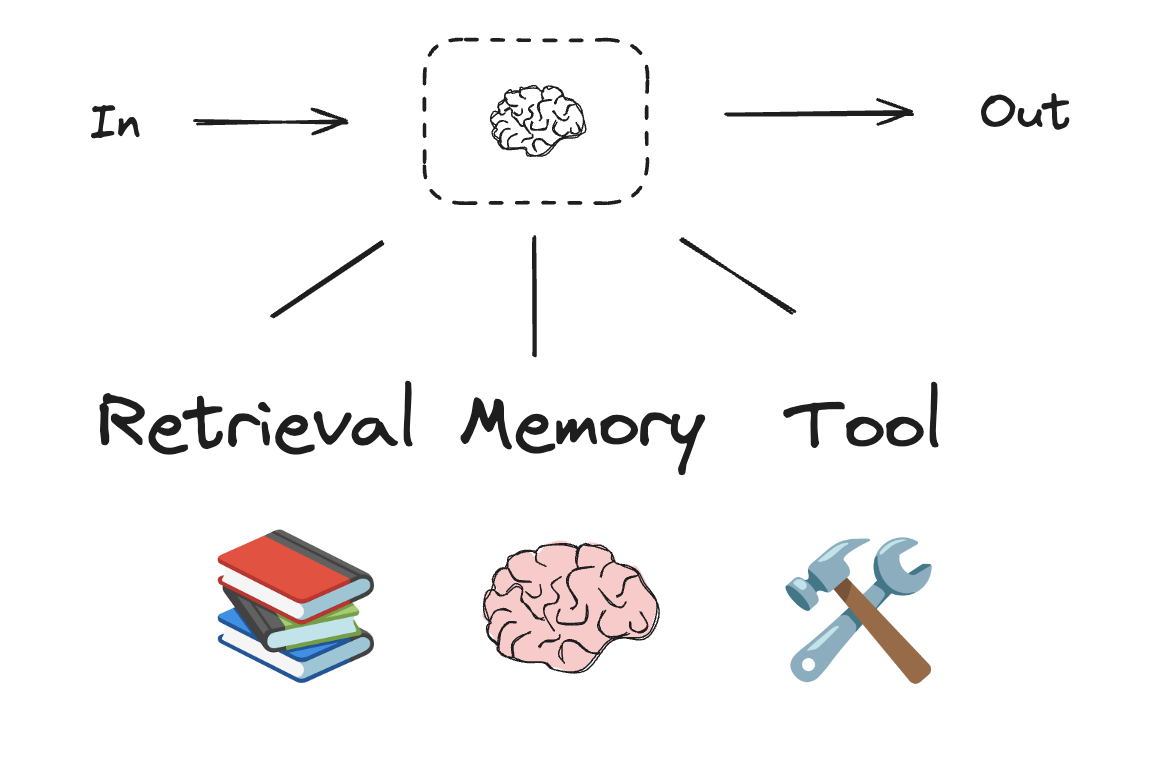
工作流和智能体系统基于 LLM 以及你为其添加的各种增强功能。工具调用、结构化输出和短期记忆是根据你的需求定制 LLM 的几种选择。
import * as z from "zod";
import { tool } from "langchain";

// 结构化输出架构
const SearchQuery = z.object({
  search_query: z.string().describe("Query that is optimized web search."),
  justification: z
    .string()
    .describe("Why this query is relevant to the user's request."),
});

// 使用结构化输出架构增强 LLM
const structuredLlm = llm.withStructuredOutput(SearchQuery);

// 调用增强后的 LLM
const output = await structuredLlm.invoke(
  "How does Calcium CT score relate to high cholesterol?"
);

// 定义工具
const multiply = tool(
  ({ a, b }) => {
    return a * b;
  },
  {
    name: "multiply",
    description: "Multiply two numbers",
    schema: z.object({
      a: z.number(),
      b: z.number(),
    }),
  }
);

// 使用工具增强 LLM
const llmWithTools = llm.bindTools([multiply]);

// 使用触发工具调用的输入调用 LLM
const msg = await llmWithTools.invoke("What is 2 times 3?");

// 获取工具调用
console.log(msg.tool_calls);
提示词链(Prompt chaining)
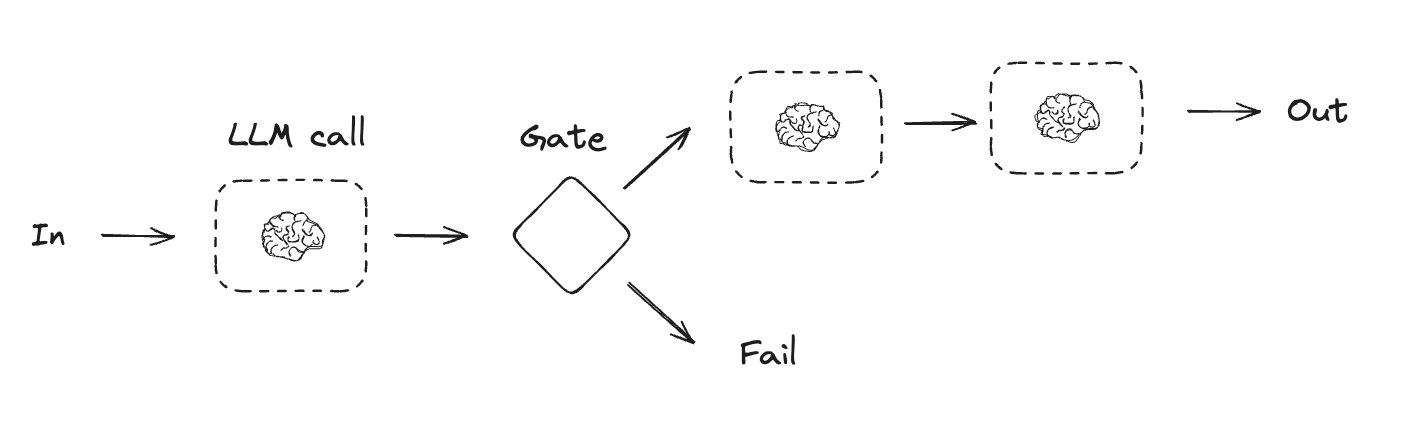
提示词链是指每个 LLM 调用处理前一个调用的输出。它通常用于执行可以分解为较小、可验证步骤的明确任务。一些示例包括:
- 将文档翻译成不同的语言
- 验证生成内容的一致性
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import { z } from "zod/v4";

// 图状态
const State = new StateSchema({
  topic: z.string(),
  joke: z.string(),
  improvedJoke: z.string(),
  finalJoke: z.string(),
});

// 定义节点函数

// 第一次 LLM 调用生成初始笑话
const generateJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a short joke about ${state.topic}`);
  return { joke: msg.content };
};

// 检查笑话是否有笑点的门禁函数
const checkPunchline: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "improveJoke" }> = (state) => {
  // 简单检查 - 笑话中是否包含 "?" 或 "!"
  if (state.joke?.includes("?") || state.joke?.includes("!")) {
    return "Pass";
  }
  return "Fail";
};

// 第二次 LLM 调用改进笑话
const improveJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(
    `Make this joke funnier by adding wordplay: ${state.joke}`
  );
  return { improvedJoke: msg.content };
};

// 第三次 LLM 调用进行最后润色
const polishJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(
    `Add a surprising twist to this joke: ${state.improvedJoke}`
  );
  return { finalJoke: msg.content };
};

// 构建工作流
const chain = new StateGraph(State)
  .addNode("generateJoke", generateJoke)
  .addNode("improveJoke", improveJoke)
  .addNode("polishJoke", polishJoke)
  .addEdge("__start__", "generateJoke")
  .addConditionalEdges("generateJoke", checkPunchline, {
    Pass: "improveJoke",
    Fail: "__end__"
  })
  .addEdge("improveJoke", "polishJoke")
  .addEdge("polishJoke", "__end__")
  .compile();

// 调用
const state = await chain.invoke({ topic: "cats" });
console.log("Initial joke:");
console.log(state.joke);
console.log("\n--- --- ---\n");
if (state.improvedJoke !== undefined) {
  console.log("Improved joke:");
  console.log(state.improvedJoke);
  console.log("\n--- --- ---\n");

  console.log("Final joke:");
  console.log(state.finalJoke);
} else {
  console.log("Joke failed quality gate - no punchline detected!");
}import { task, entrypoint } from "@langchain/langgraph";
// 任务
// 第一次 LLM 调用生成初始笑话
const generateJoke = task("generateJoke", async (topic: string) => {
const msg = await llm.invoke(`Write a short joke about ${topic}`);
return msg.content;
});
// 检查笑话是否有笑点的门禁函数
function checkPunchline(joke: string) {
// 简单检查 - 笑话是否包含 "?" 或 "!"
if (joke.includes("?") || joke.includes("!")) {
return "Pass";
}
return "Fail";
}
// 第二次 LLM 调用改进笑话
const improveJoke = task("improveJoke", async (joke: string) => {
const msg = await llm.invoke(
`Make this joke funnier by adding wordplay: ${joke}`
);
return msg.content;
});
// 第三次 LLM 调用进行最后润色
const polishJoke = task("polishJoke", async (joke: string) => {
const msg = await llm.invoke(
`Add a surprising twist to this joke: ${joke}`
);
return msg.content;
});
const workflow = entrypoint(
"jokeMaker",
async (topic: string) => {
const originalJoke = await generateJoke(topic);
if (checkPunchline(originalJoke) === "Pass") {
return originalJoke;
}
const improvedJoke = await improveJoke(originalJoke);
const polishedJoke = await polishJoke(improvedJoke);
return polishedJoke;
}
);
const stream = await workflow.streamEvents("cats", { version: "v3" });
for await (const snapshot of stream.values) {
console.log(snapshot);
}并行化(Parallelization)
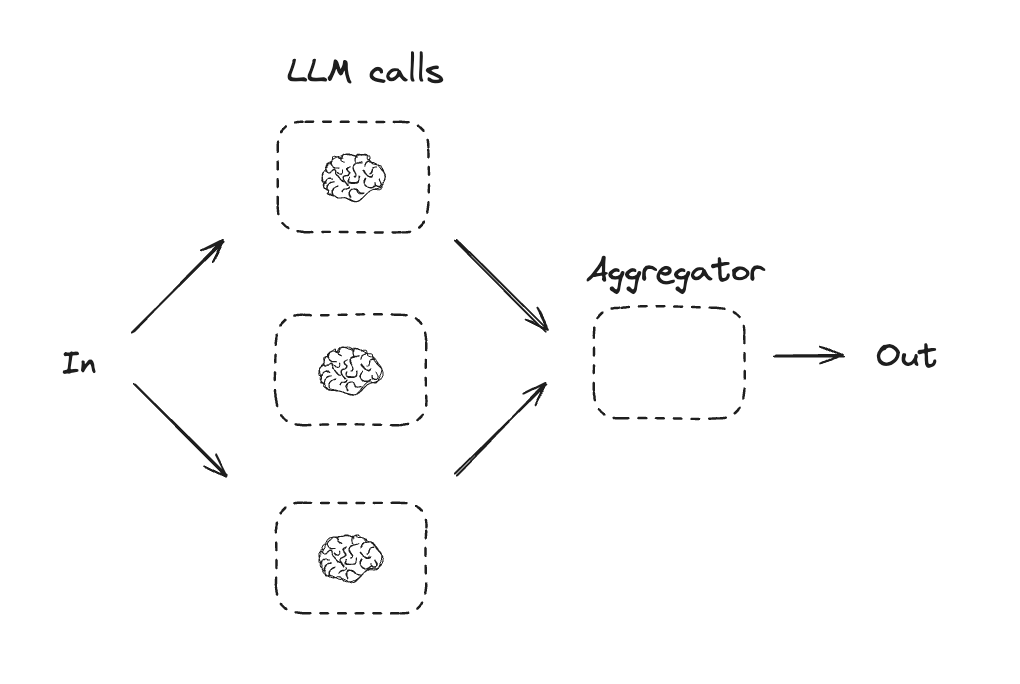
借助并行化,LLM 可以同时处理任务。这可以通过同时运行多个独立的子任务来实现,也可以通过多次运行同一任务以检查不同的输出来实现。并行化通常用于:
- 拆分子任务并并行运行它们,从而提高速度
- 多次运行任务以检查不同输出,从而提高置信度
一些示例包括:
- 运行一个处理文档关键字的子任务,以及第二个检查格式错误的子任务
- 多次运行根据不同标准(如引用次数、所用来源数量和来源质量)对文档准确性进行评分的任务
import { StateGraph, StateSchema, GraphNode } from "@langchain/langgraph";
import * as z from "zod";

// 图状态
const State = new StateSchema({
  topic: z.string(),
  joke: z.string(),
  story: z.string(),
  poem: z.string(),
  combinedOutput: z.string(),
});

// 节点
// 第一次 LLM 调用生成初始笑话
const callLlm1: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a joke about ${state.topic}`);
  return { joke: msg.content };
};

// 第二次 LLM 调用生成故事
const callLlm2: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a story about ${state.topic}`);
  return { story: msg.content };
};

// 第三次 LLM 调用生成诗歌
const callLlm3: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a poem about ${state.topic}`);
  return { poem: msg.content };
};

// 将笑话、故事和诗歌合并为单个输出
const aggregator: GraphNode<typeof State> = async (state) => {
  const combined = `Here's a story, joke, and poem about ${state.topic}!\n\n` +
    `STORY:\n${state.story}\n\n` +
    `JOKE:\n${state.joke}\n\n` +
    `POEM:\n${state.poem}`;
  return { combinedOutput: combined };
};

// 构建工作流
const parallelWorkflow = new StateGraph(State)
  .addNode("callLlm1", callLlm1)
  .addNode("callLlm2", callLlm2)
  .addNode("callLlm3", callLlm3)
  .addNode("aggregator", aggregator)
  .addEdge("__start__", "callLlm1")
  .addEdge("__start__", "callLlm2")
  .addEdge("__start__", "callLlm3")
  .addEdge("callLlm1", "aggregator")
  .addEdge("callLlm2", "aggregator")
  .addEdge("callLlm3", "aggregator")
  .addEdge("aggregator", "__end__")
  .compile();

// 调用
const result = await parallelWorkflow.invoke({ topic: "cats" });
console.log(result.combinedOutput);import { task, entrypoint } from "@langchain/langgraph";
// 任务
// 第一次 LLM 调用生成初始笑话
const callLlm1 = task("generateJoke", async (topic: string) => {
const msg = await llm.invoke(`Write a joke about ${topic}`);
return msg.content;
});
// 第二次 LLM 调用生成故事
const callLlm2 = task("generateStory", async (topic: string) => {
const msg = await llm.invoke(`Write a story about ${topic}`);
return msg.content;
});
// 第三次 LLM 调用生成诗歌
const callLlm3 = task("generatePoem", async (topic: string) => {
const msg = await llm.invoke(`Write a poem about ${topic}`);
return msg.content;
});
// 合并输出
const aggregator = task("aggregator", async (params: {
topic: string;
joke: string;
story: string;
poem: string;
}) => {
const { topic, joke, story, poem } = params;
return `Here's a story, joke, and poem about ${topic}!\n\n` +
`STORY:\n${story}\n\n` +
`JOKE:\n${joke}\n\n` +
`POEM:\n${poem}`;
});
// 构建工作流
const workflow = entrypoint(
"parallelWorkflow",
async (topic: string) => {
const [joke, story, poem] = await Promise.all([
callLlm1(topic),
callLlm2(topic),
callLlm3(topic),
]);
return aggregator({ topic, joke, story, poem });
}
);
// 调用
const stream = await workflow.streamEvents("cats", { version: "v3" });
for await (const snapshot of stream.values) {
console.log(snapshot);
}路由(Routing)
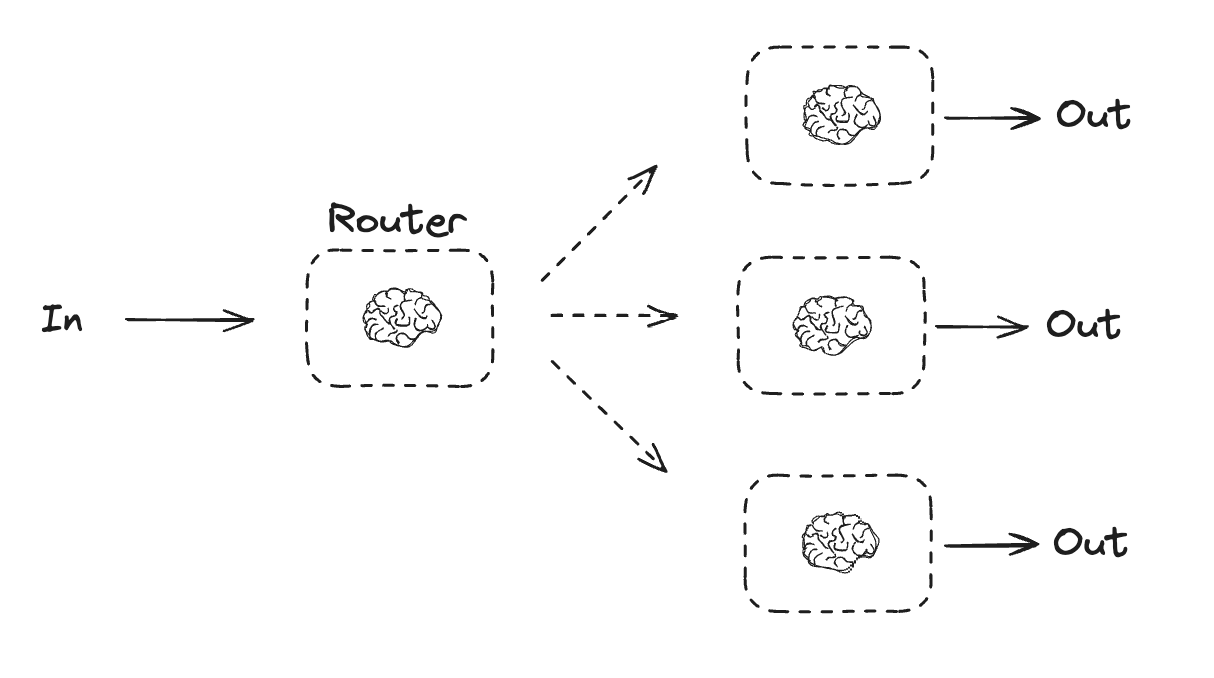
路由工作流处理输入,然后将其定向到特定于上下文的任务。这允许你为复杂任务定义专门的流程。例如,为回答产品相关问题而构建的工作流可能会首先处理问题的类型,然后将请求路由到定价、退款、退货等具体流程。
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import * as z from "zod";

// 用作路由逻辑的结构化输出架构
const routeSchema = z.object({
  step: z.enum(["poem", "story", "joke"]).describe(
    "The next step in the routing process"
  ),
});

// 使用结构化输出架构增强 LLM
const router = llm.withStructuredOutput(routeSchema);

// 图状态
const State = new StateSchema({
  input: z.string(),
  decision: z.string(),
  output: z.string(),
});

// 节点
// 写故事
const llmCall1: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert storyteller.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

// 写笑话
const llmCall2: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert comedian.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

// 写诗
const llmCall3: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert poet.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

const llmCallRouter: GraphNode<typeof State> = async (state) => {
  // 将输入路由到相应的节点
  const decision = await router.invoke([
    {
      role: "system",
      content: "Route the input to story, joke, or poem based on the user's request."
    },
    {
      role: "user",
      content: state.input
    },
  ]);

  return { decision: decision.step };
};

// 路由到相应节点的条件边函数
const routeDecision: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCall1" | "llmCall2" | "llmCall3" }> = (state) => {
  // 返回你接下来要访问的节点名称
  if (state.decision === "story") {
    return "llmCall1";
  } else if (state.decision === "joke") {
    return "llmCall2";
  } else {
    return "llmCall3";
  }
};

// 构建工作流
const routerWorkflow = new StateGraph(State)
  .addNode("llmCall1", llmCall1)
  .addNode("llmCall2", llmCall2)
  .addNode("llmCall3", llmCall3)
  .addNode("llmCallRouter", llmCallRouter)
  .addEdge("__start__", "llmCallRouter")
  .addConditionalEdges(
    "llmCallRouter",
    routeDecision,
    ["llmCall1", "llmCall2", "llmCall3"],
  )
  .addEdge("llmCall1", "__end__")
  .addEdge("llmCall2", "__end__")
  .addEdge("llmCall3", "__end__")
  .compile();

// 调用
const state = await routerWorkflow.invoke({
  input: "Write me a joke about cats"
});
console.log(state.output);import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";
// 用作路由逻辑的结构化输出架构
const routeSchema = z.object({
step: z.enum(["poem", "story", "joke"]).describe(
"The next step in the routing process"
),
});
// 使用结构化输出架构增强 LLM
const router = llm.withStructuredOutput(routeSchema);
// 任务
// 写故事
const llmCall1 = task("generateStory", async (input: string) => {
const result = await llm.invoke([{
role: "system",
content: "You are an expert storyteller.",
}, {
role: "user",
content: input
}]);
return result.content;
});
// 写笑话
const llmCall2 = task("generateJoke", async (input: string) => {
const result = await llm.invoke([{
role: "system",
content: "You are an expert comedian.",
}, {
role: "user",
content: input
}]);
return result.content;
});
// 写诗
const llmCall3 = task("generatePoem", async (input: string) => {
const result = await llm.invoke([{
role: "system",
content: "You are an expert poet.",
}, {
role: "user",
content: input
}]);
return result.content;
});
// 将输入路由到相应的节点
const llmCallRouter = task("router", async (input: string) => {
const decision = await router.invoke([
{
role: "system",
content: "Route the input to story, joke, or poem based on the user's request."
},
{
role: "user",
content: input
},
]);
return decision.step;
});
// 构建工作流
const workflow = entrypoint(
"routerWorkflow",
async (input: string) => {
const nextStep = await llmCallRouter(input);
let llmCall;
if (nextStep === "story") {
llmCall = llmCall1;
} else if (nextStep === "joke") {
llmCall = llmCall2;
} else if (nextStep === "poem") {
llmCall = llmCall3;
}
const finalResult = await llmCall(input);
return finalResult;
}
);
// 调用
const stream = await workflow.streamEvents("Write me a joke about cats", { version: "v3" });
for await (const snapshot of stream.values) {
console.log(snapshot);
}编排者-工作者(Orchestrator-worker)
在编排者-工作者配置中,编排者:
- 将任务分解为子任务
- 将子任务委托给工作者(workers)
- 将工作者输出合成为最终结果
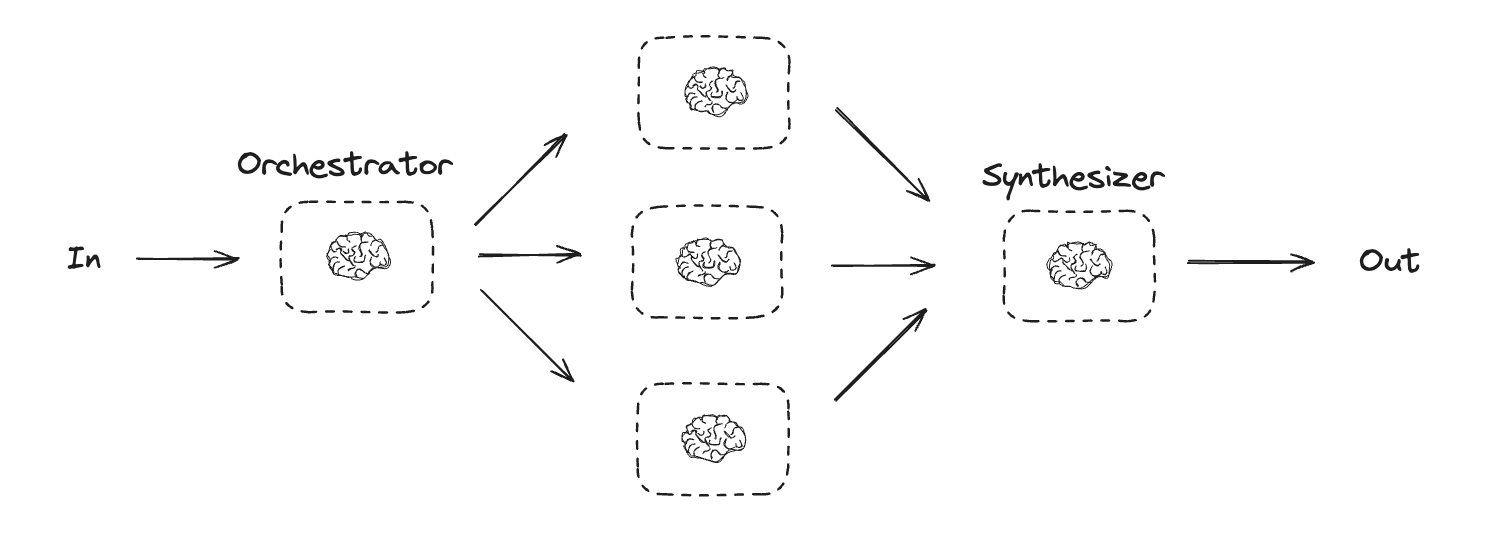
编排者-工作者工作流提供了更大的灵活性,通常在子任务无法像并行化那样预先定义时使用。这在编写代码或需要更新跨多个文件内容的工作流中很常见。例如,需要在未知数量的文档中更新多个 Python 库的安装说明的工作流可能会使用此模式。
import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";

// 用于规划的结构化输出架构
const sectionSchema = z.object({
  name: z.string().describe("Name for this section of the report."),
  description: z.string().describe(
    "Brief overview of the main topics and concepts to be covered in this section."
  ),
});

const sectionsSchema = z.object({
  sections: z.array(sectionSchema).describe("Sections of the report."),
});

// 使用结构化输出架构增强 LLM
const planner = llm.withStructuredOutput(sectionsSchema);

// 任务
const orchestrator = task("orchestrator", async (topic: string) => {
  // 生成查询
  const reportSections = await planner.invoke([
    { role: "system", content: "Generate a plan for the report." },
    { role: "user", content: `Here is the report topic: ${topic}` },
  ]);

  return reportSections.sections;
});

const llmCall = task("sectionWriter", async (section: z.infer<typeof sectionSchema>) => {
  // 生成章节
  const result = await llm.invoke([
    {
      role: "system",
      content: "Write a report section.",
    },
    {
      role: "user",
      content: `Here is the section name: ${section.name} and description: ${section.description}`,
    },
  ]);

  return result.content;
});

const synthesizer = task("synthesizer", async (completedSections: string[]) => {
  // 从章节合成完整报告
  return completedSections.join("\n\n---\n\n");
});

// 构建工作流
const workflow = entrypoint(
  "orchestratorWorker",
  async (topic: string) => {
    const sections = await orchestrator(topic);
    const completedSections = await Promise.all(
      sections.map((section) => llmCall(section))
    );
    return synthesizer(completedSections);
  }
);

// 调用
const stream = await workflow.streamEvents("Create a report on LLM scaling laws", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
在 LangGraph 中创建工作者
编排者-工作者工作流非常普遍,LangGraph 对其提供了内置支持。Send API 允许你动态创建工作者节点并向其发送特定的输入。每个工作者都有自己的状态,所有工作者的输出都会写入可由编排者图访问的共享状态键中。这使编排者能够访问所有工作者的输出并将其合成最终输出。以下示例遍历章节列表并使用 Send API 将章节发送给各个工作者。
import { StateGraph, StateSchema, ReducedValue, GraphNode, Send, ConditionalEdgeRouter } from "@langchain/langgraph";
import * as z from "zod";

type SectionSchema = {
  name: string;
  description: string;
};
type SectionsSchema = {
  sections: SectionSchema[];
};

// 图状态
const State = new StateSchema({
  topic: z.string(),
  sections: z.array(z.custom<SectionSchema>()),
  completedSections: new ReducedValue(
    z.array(z.string()).default(() => []),
    { reducer: (a, b) => a.concat(b) }
  ),
  finalReport: z.string(),
});

// 工作者状态
const WorkerState = new StateSchema({
  section: z.custom<SectionSchema>(),
  completedSections: new ReducedValue(
    z.array(z.string()).default(() => []),
    { reducer: (a, b) => a.concat(b) }
  ),
});

// 节点
const orchestrator: GraphNode<typeof State> = async (state) => {
  // 生成查询
  const reportSections = await planner.invoke([
    { role: "system", content: "Generate a plan for the report." },
    { role: "user", content: `Here is the report topic: ${state.topic}` },
  ]);

  return { sections: reportSections.sections };
};

const llmCall: GraphNode<typeof WorkerState> = async (state) => {
  // 生成章节
  const section = await llm.invoke([
    {
      role: "system",
      content: "Write a report section following the provided name and description. Include no preamble for each section. Use markdown formatting.",
    },
    {
      role: "user",
      content: `Here is the section name: ${state.section.name} and description: ${state.section.description}`,
    },
  ]);

  // 将更新后的章节写入已完成章节
  return { completedSections: [section.content] };
};

const synthesizer: GraphNode<typeof State> = async (state) => {
  // 已完成章节列表
  const completedSections = state.completedSections;

  // 将已完成的章节格式化为字符串,用作最终章节的上下文
  const completedReportSections = completedSections.join("\n\n---\n\n");

  return { finalReport: completedReportSections };
};

// 用于创建各自编写报告一章的 llm_call 工作者的条件边函数
const assignWorkers: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCall" }> = (state) => {
  // 通过 Send() API 并行触发章节编写
  return state.sections.map((section) =>
    new Send("llmCall", { section })
  );
};

// 构建工作流
const orchestratorWorker = new StateGraph(State)
  .addNode("orchestrator", orchestrator)
  .addNode("llmCall", llmCall)
  .addNode("synthesizer", synthesizer)
  .addEdge("__start__", "orchestrator")
  .addConditionalEdges(
    "orchestrator",
    assignWorkers,
    ["llmCall"]
  )
  .addEdge("llmCall", "synthesizer")
  .addEdge("synthesizer", "__end__")
  .compile();

// 调用
const state = await orchestratorWorker.invoke({
  topic: "Create a report on LLM scaling laws"
});
console.log(state.finalReport);
评估者-优化者(Evaluator-optimizer)
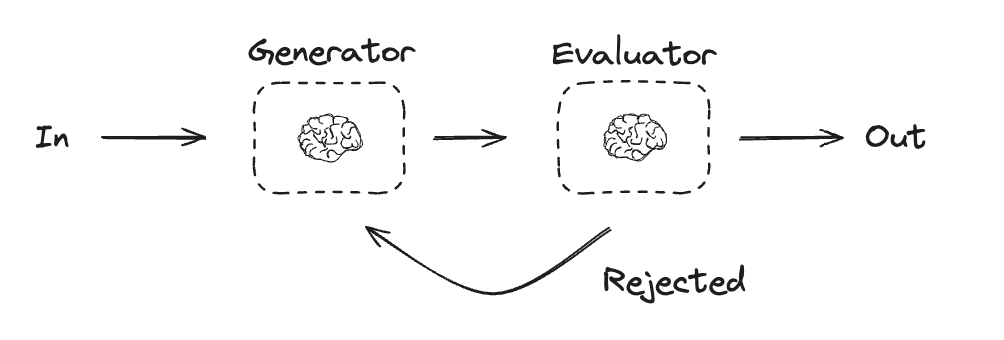
在评估者-优化者工作流中,一个 LLM 调用创建响应,另一个评估该响应。如果评估者或人机协同确定响应需要改进,则会提供反馈并重新创建响应。此循环一直持续到生成可接受的响应。
当任务有特定的成功标准,但需要迭代才能满足该标准时,通常使用评估者-优化者工作流。例如,在两种语言之间翻译文本时并不总是有完美的匹配。可能需要进行几次迭代才能生成在两种语言中具有相同含义的翻译。
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import * as z from "zod";

// 图状态
const State = new StateSchema({
  joke: z.string(),
  topic: z.string(),
  feedback: z.string(),
  funnyOrNot: z.string(),
});

// 用于评估的结构化输出架构
const feedbackSchema = z.object({
  grade: z.enum(["funny", "not funny"]).describe(
    "Decide if the joke is funny or not."
  ),
  feedback: z.string().describe(
    "If the joke is not funny, provide feedback on how to improve it."
  ),
});

// 使用结构化输出架构增强 LLM
const evaluator = llm.withStructuredOutput(feedbackSchema);

// 节点
const llmCallGenerator: GraphNode<typeof State> = async (state) => {
  // LLM 生成笑话
  let msg;
  if (state.feedback) {
    msg = await llm.invoke(
      `Write a joke about ${state.topic} but take into account the feedback: ${state.feedback}`
    );
  } else {
    msg = await llm.invoke(`Write a joke about ${state.topic}`);
  }
  return { joke: msg.content };
};

const llmCallEvaluator: GraphNode<typeof State> = async (state) => {
  // LLM 评估笑话
  const grade = await evaluator.invoke(`Grade the joke ${state.joke}`);
  return { funnyOrNot: grade.grade, feedback: grade.feedback };
};

// 根据评估者的反馈路由回笑话生成器或结束的条件边函数
const routeJoke: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCallGenerator" }> = (state) => {
  // 根据评估者的反馈路由回笑话生成器或结束
  if (state.funnyOrNot === "funny") {
    return "Accepted";
  } else {
    return "Rejected + Feedback";
  }
};

// 构建工作流
const optimizerWorkflow = new StateGraph(State)
  .addNode("llmCallGenerator", llmCallGenerator)
  .addNode("llmCallEvaluator", llmCallEvaluator)
  .addEdge("__start__", "llmCallGenerator")
  .addEdge("llmCallGenerator", "llmCallEvaluator")
  .addConditionalEdges(
    "llmCallEvaluator",
    routeJoke,
    {
      // routeJoke 返回的名称 : 下一个要访问的节点名称
      "Accepted": "__end__",
      "Rejected + Feedback": "llmCallGenerator",
    }
  )
  .compile();

// 调用
const state = await optimizerWorkflow.invoke({ topic: "Cats" });
console.log(state.joke);import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";
// 用于评估的结构化输出架构
const feedbackSchema = z.object({
grade: z.enum(["funny", "not funny"]).describe(
"Decide if the joke is funny or not."
),
feedback: z.string().describe(
"If the joke is not funny, provide feedback on how to improve it."
),
});
// 使用结构化输出架构增强 LLM
const evaluator = llm.withStructuredOutput(feedbackSchema);
// 任务
const llmCallGenerator = task("jokeGenerator", async (params: {
topic: string;
feedback?: z.infer<typeof feedbackSchema>;
}) => {
// LLM 生成笑话
const msg = params.feedback
? await llm.invoke(
`Write a joke about ${params.topic} but take into account the feedback: ${params.feedback.feedback}`
)
: await llm.invoke(`Write a joke about ${params.topic}`);
return msg.content;
});
const llmCallEvaluator = task("jokeEvaluator", async (joke: string) => {
// LLM 评估笑话
return evaluator.invoke(`Grade the joke ${joke}`);
});
// 构建工作流
const workflow = entrypoint(
"optimizerWorkflow",
async (topic: string) => {
let feedback: z.infer<typeof feedbackSchema> | undefined;
let joke: string;
while (true) {
joke = await llmCallGenerator({ topic, feedback });
feedback = await llmCallEvaluator(joke);
if (feedback.grade === "funny") {
break;
}
}
return joke;
}
);
// 调用
const stream = await workflow.streamEvents("Cats", { version: "v3" });
for await (const snapshot of stream.values) {
console.log(snapshot);
console.log("\n");
}智能体(Agents)
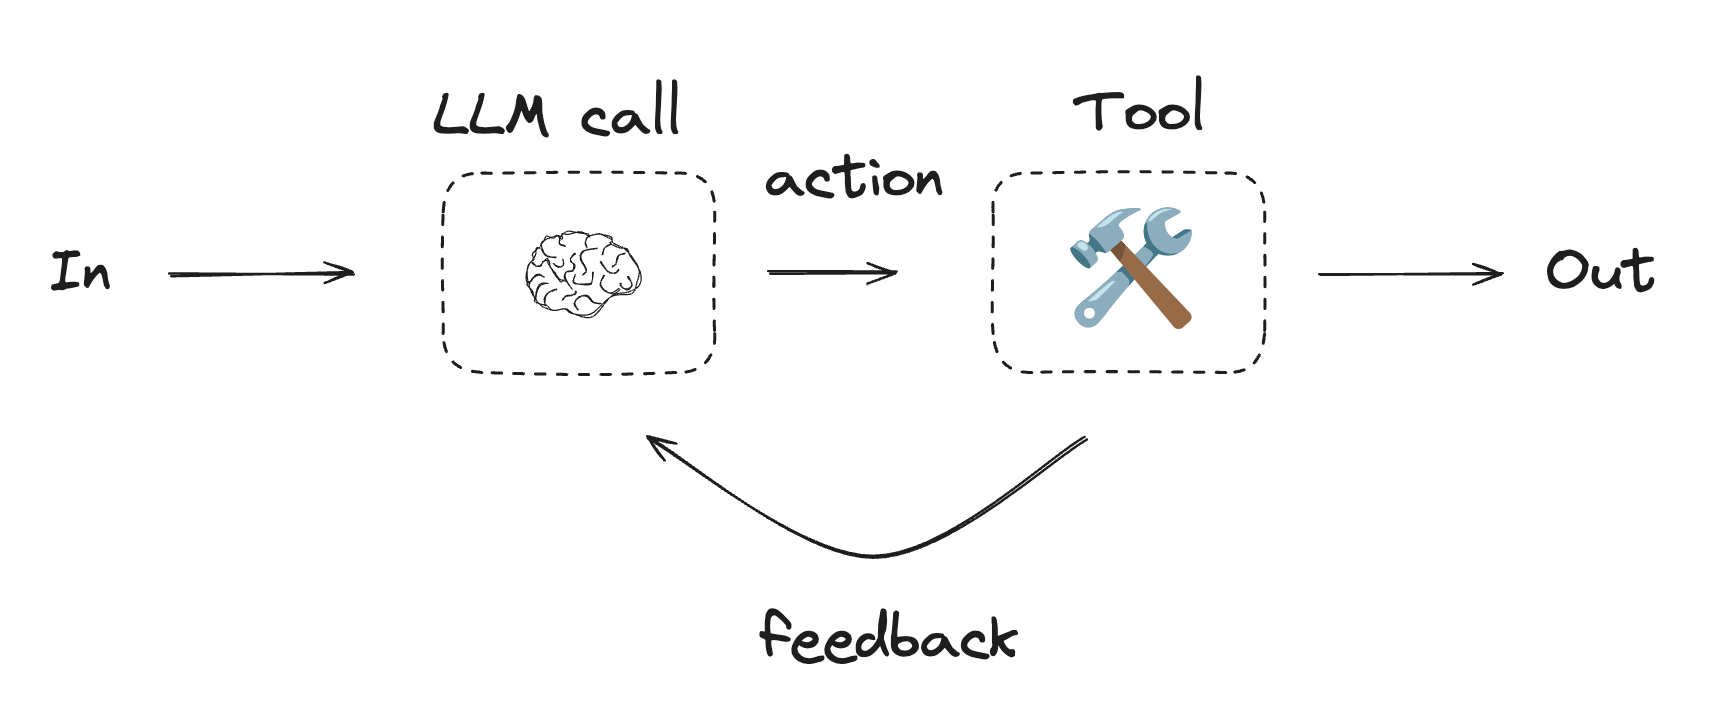
智能体通常实现为使用工具执行操作的 LLM。它们在持续的反馈循环中运行,并在问题和解决方案不可预测的情况下使用。智能体比工作流拥有更多的自主权,可以就所使用的工具以及如何解决问题做出决策。你仍然可以定义可用的工具集以及智能体行为的准则。
// 使用工具
import { tool } from "@langchain/core/tools";
import * as z from "zod";

// 定义工具
const multiply = tool(
  ({ a, b }) => {
    return a * b;
  },
  {
    name: "multiply",
    description: "Multiply two numbers together",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

const add = tool(
  ({ a, b }) => {
    return a + b;
  },
  {
    name: "add",
    description: "Add two numbers together",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

const divide = tool(
  ({ a, b }) => {
    return a / b;
  },
  {
    name: "divide",
    description: "Divide two numbers",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

// 使用工具增强 LLM
const tools = [add, multiply, divide];
const toolsByName = Object.fromEntries(tools.map((tool) => [tool.name, tool]));
const llmWithTools = llm.bindTools(tools);import { StateGraph, StateSchema, MessagesValue, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import { ToolNode } from "@langchain/langgraph/prebuilt";
import {
SystemMessage,
ToolMessage
} from "@langchain/core/messages";
// 图状态
const State = new StateSchema({
messages: MessagesValue,
});
// 节点
const llmCall: GraphNode<typeof State> = async (state) => {
// LLM 决定是否调用工具
const result = await llmWithTools.invoke([
{
role: "system",
content: "You are a helpful assistant tasked with performing arithmetic on a set of inputs."
},
...state.messages
]);
return {
messages: [result]
};
};
const toolNode = new ToolNode(tools);
// 路由到工具节点或结束的条件边函数
const shouldContinue: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "toolNode" }> = (state) => {
const messages = state.messages;
const lastMessage = messages.at(-1);
// 如果 LLM 发起了工具调用,则执行操作
if (lastMessage?.tool_calls?.length) {
return "toolNode";
}
// 否则,停止(回复用户)
return "__end__";
};
// 构建工作流
const agentBuilder = new StateGraph(State)
.addNode("llmCall", llmCall)
.addNode("toolNode", toolNode)
// 添加连接节点的边
.addEdge("__start__", "llmCall")
.addConditionalEdges(
"llmCall",
shouldContinue,
["toolNode", "__end__"]
)
.addEdge("toolNode", "llmCall")
.compile();
// 调用
const messages = [{
role: "user",
content: "Add 3 and 4."
}];
const result = await agentBuilder.invoke({ messages });
console.log(result.messages);import { task, entrypoint, addMessages } from "@langchain/langgraph";
import { BaseMessageLike, ToolCall } from "@langchain/core/messages";
const callLlm = task("llmCall", async (messages: BaseMessageLike[]) => {
// LLM 决定是否调用工具
return llmWithTools.invoke([
{
role: "system",
content: "You are a helpful assistant tasked with performing arithmetic on a set of inputs."
},
...messages
]);
});
const callTool = task("toolCall", async (toolCall: ToolCall) => {
// 执行工具调用
const tool = toolsByName[toolCall.name];
return tool.invoke(toolCall.args);
});
const agent = entrypoint(
"agent",
async (messages) => {
let llmResponse = await callLlm(messages);
while (true) {
if (!llmResponse.tool_calls?.length) {
break;
}
// 执行工具
const toolResults = await Promise.all(
llmResponse.tool_calls.map((toolCall) => callTool(toolCall))
);
messages = addMessages(messages, [llmResponse, ...toolResults]);
llmResponse = await callLlm(messages);
}
messages = addMessages(messages, [llmResponse]);
return messages;
}
);
// 调用
const messages = [{
role: "user",
content: "Add 3 and 4."
}];
const stream = await agent.streamEvents([messages], { version: "v3" });
for await (const snapshot of stream.values) {
console.log(snapshot);
}ToolNode
ToolNode 是一个在 LangGraph 工作流中执行工具的预构建节点。它自动处理并行工具执行、错误处理和状态注入。
当你需要对图如何执行工具进行细粒度控制时,请使用 ToolNode。这是为许多 LangGraph 智能体模式中的工具执行提供支持的基础构建块。
import { ToolNode } from "@langchain/langgraph/prebuilt";
import { tool } from "@langchain/core/tools";
import * as z from "zod";

const search = tool(
  ({ query }) => `Results for: ${query}`,
  {
    name: "search",
    description: "Search for information.",
    schema: z.object({ query: z.string() }),
  }
);

const calculator = tool(
  ({ expression }) => String(eval(expression)),
  {
    name: "calculator",
    description: "Evaluate a math expression.",
    schema: z.object({ expression: z.string() }),
  }
);

const toolNode = new ToolNode([search, calculator]);
从工具中访问图状态和上下文
由 ToolNode 执行的工具接收模型生成的参数作为其第一个参数。若要读取非模型生成的图端数据,请使用以下选项之一:
- 在 Python 中,从注入的
ToolRuntime参数中读取状态和运行范围的上下文。 - 在 JavaScript 中,从工具的第二个参数中读取状态和运行范围的上下文,类型为
ToolRuntime。
INFO
工具只能访问传递给 ToolNode 的状态值。当 ToolNode 直接作为 StateGraph 节点添加时,该输入即为当前图状态。如果你从另一个节点手动调用 ToolNode,并且工具需要自定义状态字段,请传递完整的状态。例如,tool_node.invoke(state) 或 toolNode.invoke(state, config) 会暴露完整状态,而仅传递 {"messages": state["messages"]} 或 { messages: state.messages } 则只会暴露 messages。
import { AIMessage } from "@langchain/core/messages";
import { tool, type ToolRuntime } from "@langchain/core/tools";
import {
  MessagesValue,
  START,
  StateGraph,
  StateSchema,
} from "@langchain/langgraph";
import { ToolNode } from "@langchain/langgraph/prebuilt";
import * as z from "zod";

const State = new StateSchema({
  messages: MessagesValue,
  userId: z.string(),
});

const ContextSchema = z.object({
  organizationId: z.string(),
});

const getUserInfo = tool(
  async (
    _input,
    runtime: ToolRuntime<typeof State.Type, typeof ContextSchema>,
  ) => {
    // 读取传递给 ToolNode 的当前图状态。
    const userIdFromState = runtime.state?.userId;
    const userIdFromTaskInput = (
      runtime.configurable as {
        __pregel_scratchpad?: { currentTaskInput?: { userId?: string } };
      }
    ).__pregel_scratchpad?.currentTaskInput?.userId;
    const userId = userIdFromState ?? userIdFromTaskInput;
    if (!userId) {
      throw new Error("Missing userId in ToolRuntime state.");
    }

    // 将运行时上下文用于不属于图状态的显式单次运行值。
    const organizationId = runtime.context.organizationId;

    return `User ${userId} in organization ${organizationId}`;
  },
  {
    name: "get_user_info",
    description: "Look up user information.",
    schema: z.object({}),
  },
);

const graph = new StateGraph(State, ContextSchema)
  .addNode("tools", new ToolNode([getUserInfo]))
  .addEdge(START, "tools")
  .compile();

const result = await graph.invoke(
  {
    messages: [
      new AIMessage({
        content: "",
        tool_calls: [{ name: "get_user_info", args: {}, id: "call_user_info" }],
      }),
    ],
    userId: "user_123",
  },
  { context: { organizationId: "org_456" } },
);为此示例打开公开的 LangSmith 运行记录。