
存储(Stores)
LangGraph 存储提供跨线程长期记忆,补充基于单线程的检查点持久化。
存储(Stores)允许智能体跨线程持久化信息,包括用户偏好、积累的知识以及应该在单次对话之后继续保留的事实。与将完整图状态限定在单个线程范围内的检查点保存器不同,存储保存可从任何线程访问的任意键值数据。
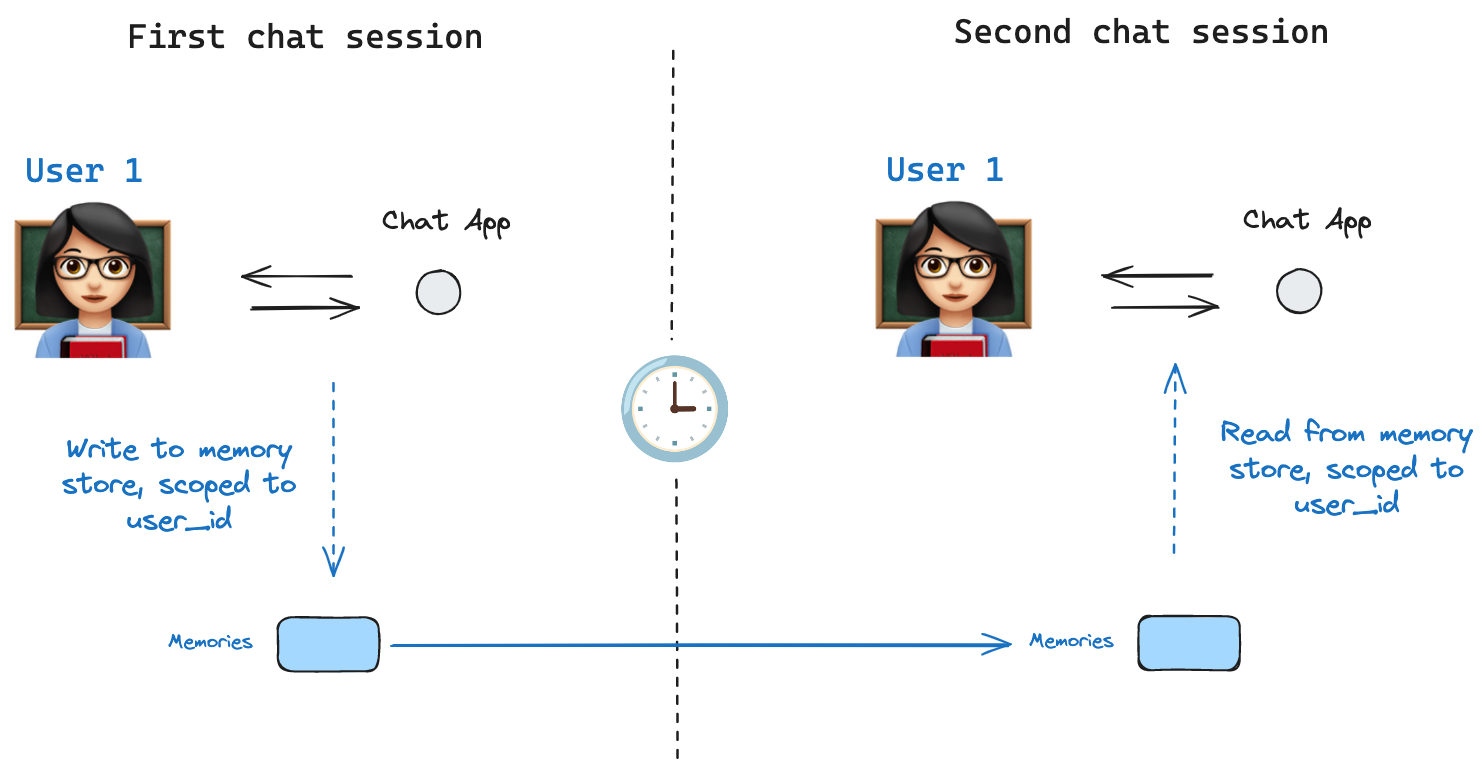
INFO
Agent Server 自动处理存储 使用 Agent Server 时,你无需手动实现或配置存储。API 在后台为你处理所有存储基础设施。
INFO
InMemoryStore 适用于开发和测试。对于生产环境,请使用持久化存储,如 PostgresStore、MongoDBStore、RedisStore 或 UpstashStore。所有实现均扩展自 BaseStore,这是在节点函数签名中使用的类型注解。
INFO
有关可用提供商的完整列表,请参阅存储集成。
基本用法
以下代码片段展示了脱离 LangGraph 单独使用的 InMemoryStore:
import { InMemoryStore } from "@langchain/langgraph";

const memoryStore = new InMemoryStore();
记忆通过元组设置命名空间,在以下示例中为 (<user_id>, "memories")。命名空间可以是任意长度并代表任何内容,不必特定于用户。
const userId = "1";
const namespaceForMemory = [userId, "memories"];
使用 store.put 方法将记忆保存到存储中的命名空间。指定上述定义的命名空间,以及记忆的键值对:键只是记忆的唯一标识符(memory_id),值(字典对象)是记忆本身。
import { v7 as uuid7 } from "uuid";
const memoryId = uuid7();
const memory = { food_preference: "I like pizza" };
await memoryStore.put(namespaceForMemory, memoryId, memory);
使用 store.search 方法从命名空间读取记忆,该方法以列表形式返回给定用户的记忆,最多可达到 limit 参数的数量(默认 10)。使用 InMemoryStore 时,项目按插入顺序返回,因此最新的记忆排在列表末尾;其他后端对记忆的排序可能不同(请参阅列出命名空间中的项目)。
const memories = await memoryStore.search(namespaceForMemory);
memories[memories.length - 1];

// {
//   value: { food_preference: 'I like pizza' },
//   key: '07e0caf4-1631-47b7-b15f-65515d4c1843',
//   namespace: ['1', 'memories'],
//   createdAt: '2024-10-02T17:22:31.590602+00:00',
//   updatedAt: '2024-10-02T17:22:31.590605+00:00'
// }
它包含的属性有:
value:此记忆的值key:此记忆在命名空间中的唯一键namespace:字符串元组,此记忆类型的命名空间INFO
虽然类型是
tuple,但在转换为 JSON 时可能会序列化为列表(例如['1', 'memories'])。createdAt:创建此记忆的时间戳updatedAt:更新此记忆的时间戳
列出命名空间中的项目
在不传递 query 且不传递 filter 的情况下调用 store.search 会返回存储在命名空间前缀下的项目,最多可达 limit。当你不需要语义排序时,可以使用此方法枚举命名空间中的所有内容。
// 返回存储在 ["alice", "memories"] 下的最多 100 个项目。
const items = await store.search(["alice", "memories"], { limit: 100 });
需要注意的三种行为:
namespace_prefix按前缀匹配,而不是完全匹配。("alice",)还会返回("alice", "memories")、("alice", "preferences")等下的项目。若要限制为单个级别,请传递完整命名空间或在客户端根据item.namespace过滤返回的项目。- 超出
limit的结果会被静默截断。 没有溢出信号——请将limit设置为高于你的预期最大值,或使用offset进行分页。 - 默认排序取决于存储后端。
PostgresStore和AsyncPostgresStore返回按updated_at降序排序的结果(最近更新的排在前面)。InMemoryStore按插入顺序返回结果(最近插入的排在最后)。不要依赖跨实现的特定顺序;如果顺序很重要,请在客户端根据item.updated_at进行排序。
要对大型命名空间进行分页:
const pageSize = 50;
let offset = 0;
while (true) {
  const page = await store.search(["alice", "memories"], { limit: pageSize, offset });
  if (page.length === 0) break;
  for (const item of page) {
    // ...
  }
  offset += pageSize;
}
若要发现存在哪些命名空间(例如在列出用户的记忆之前遍历每个用户),请使用 store.listNamespaces:
// 以 ["alice"] 开头的所有命名空间,截断为两层深度。
const namespaces = await store.listNamespaces({ prefix: ["alice"], maxDepth: 2 });
语义搜索(Semantic search)
除了简单检索之外,存储还支持语义搜索,允许你根据含义而不是完全匹配来查找记忆。要启用此功能,请使用嵌入模型配置存储:
import { OpenAIEmbeddings } from "@langchain/openai";

const store = new InMemoryStore({
  index: {
    embeddings: new OpenAIEmbeddings({ model: "text-embedding-3-small" }),
    dims: 1536,
    fields: ["food_preference", "$"], // 要嵌入的字段
  },
});
现在搜索时,你可以使用自然语言查询来查找相关记忆:
// 查找有关食物偏好的记忆
// (这可以在将记忆存入存储后完成)
const memories = await store.search(namespaceForMemory, {
  query: "What does the user like to eat?",
  limit: 3, // 返回前 3 个匹配项
});
你可以通过配置 fields 参数或在存储记忆时指定 index 参数来控制嵌入记忆的哪些部分:
// 存储要嵌入的特定字段
await store.put(
  namespaceForMemory,
  uuid7(),
  {
    food_preference: "I love Italian cuisine",
    context: "Discussing dinner plans",
  },
  { index: ["food_preference"] } // 仅嵌入 "food_preferences" 字段
);

import { v7 as uuid7 } from "uuid";
// 存储但不进行嵌入(仍然可以检索,但不可搜索)
await store.put(
  namespaceForMemory,
  uuid7(),
  { system_info: "Last updated: 2024-01-01" },
  { index: false }
);
在 LangGraph 中使用
memoryStore 与检查点保存器协同工作:检查点保存器将状态保存到线程(如上所述),而 memoryStore 允许你存储任意信息以供跨线程访问。按照如下方式使用检查点保存器和 memoryStore 编译图。
import { MemorySaver } from "@langchain/langgraph";

// 我们需要这个,因为我们想要启用线程(对话)
const checkpointer = new MemorySaver();

// ... 定义图 ...

// 使用检查点保存器和存储编译图
const graph = workflow.compile({ checkpointer, store: memoryStore });
然后像以前一样使用 thread_id 调用图,并且还带有 user_id,它像以前一样用作该特定用户的记忆命名空间。
// 调用图
const userId = "1";
const config = { configurable: { thread_id: "1" }, context: { userId } };

// 首先向 AI 打个招呼
for await (const update of await graph.stream(
  { messages: [{ role: "user", content: "hi" }] },
  { ...config, streamMode: "updates" }
)) {
  console.log(update);
}
你可以通过 runtime 参数从任何节点访问存储和 userId。你可以使用它来保存记忆:
import { StateSchema, MessagesValue, Runtime, GraphNode } from "@langchain/langgraph";
import { v7 as uuid7 } from "uuid";

const MessagesState = new StateSchema({
  messages: MessagesValue,
});

const updateMemory: GraphNode<typeof MessagesState> = async (state, runtime) => {
  // 从配置中获取用户 ID
  const userId = runtime.context?.user_id;
  if (!userId) throw new Error("User ID is required");

  // 为记忆设置命名空间
  const namespace = [userId, "memories"];

  // ... 分析对话并创建新记忆
  const memory = "Some memory content";

  // 创建新记忆 ID
  const memoryId = uuid7();

  // 我们创建新记忆
  await runtime.store?.put(namespace, memoryId, { memory });
};
你还可以从任何节点访问存储并使用 store.search 方法获取记忆。记忆作为可以转换为字典的对象列表返回。
memories[memories.length - 1];
// {
//   value: { food_preference: 'I like pizza' },
//   key: '07e0caf4-1631-47b7-b15f-65515d4c1843',
//   namespace: ['1', 'memories'],
//   createdAt: '2024-10-02T17:22:31.590602+00:00',
//   updatedAt: '2024-10-02T17:22:31.590605+00:00'
// }
你访问记忆并在模型调用中使用它们。
const callModel: GraphNode<typeof MessagesState> = async (state, runtime) => {
  // 从配置中获取用户 ID
  const userId = runtime.context?.user_id;

  // 为记忆设置命名空间
  const namespace = [userId, "memories"];

  // 根据最新消息进行搜索
  const memories = await runtime.store?.search(namespace, {
    query: state.messages[state.messages.length - 1].content,
    limit: 3,
  });
  const info = memories.map((d) => d.value.memory).join("\n");

  // ... 在模型调用中使用记忆
};
如果你创建一个新线程,只要 user_id 相同,你仍然可以访问相同的记忆。
// 调用图
const config = { configurable: { thread_id: "2" }, context: { userId: "1" } };

// 让我们再次打招呼
for await (const update of await graph.stream(
  { messages: [{ role: "user", content: "hi, tell me about my memories" }] },
  { ...config, streamMode: "updates" }
)) {
  console.log(update);
}
当你在本地使用 LangSmith(例如在 Studio 中)或在托管版中使用时,基础存储默认可用,你无需在图编译期间指定它。但是,若要启用语义搜索,你确实需要在 langgraph.json 文件中配置索引设置。例如:
{
    "store": {
        "index": {
            "embed": "openai:text-embeddings-3-small",
            "dims": 1536,
            "fields": ["$"]
        }
    }
}有关更多详细信息和配置选项,请参阅部署指南。
后续步骤
- 向 Agent Server 添加自定义存储 — 部署你的实现
- 检查点 — 线程范围的状态持久化